外观主题
Antigravity CLI 压缩后无损回水(Post-Compact Rehydration)与跨 /fork 溯源方案
本文档介绍一套面向 Antigravity CLI(agy)的零侵入全局 PreInvocation Hook 方案(~/.gemini/config/hooks.json + ~/.gemini/config/hooks/rehydrate_after_compact.py),用于彻底解决长会话自动压缩与手动 /compact 后的上下文“断忆”问题,并支持跨 /fork 分支自动回溯父会话历史。
1. 背景:为什么原生 /compact 与 256K 自动压缩会“失忆”?
在 Antigravity CLI 中,当单轮上下文累计(input_tokens + cache_read_tokens)跨过约 256 Ki tokens(262,144),或用户手动执行 /compact 时,底层 Harness 会在会话日志中写入一条 type == "CHECKPOINT" 记录,并用一段单次生成的 <CONTEXT_SUMMARY> 替换早期历史。
原生压缩机制存在三个结构性损耗点:
仅保留概括摘要与最近 10 条提问:
<CONTEXT_SUMMARY>只保留最近 10 条用户消息,超过 10 轮的早期全局约束(如目录边界、环境规范、超参或排版约定)容易在摘要改写中被弱化甚至遗漏。源码上下文与工具轨迹彻底清空:压缩前通过
read_file读过的关键代码、SKILL.md/SPEC/PLAN文档以及压缩前最后几轮的精确对话措辞全部从上下文中消失,导致压缩后模型容易凭印象猜测接口或重复已完成排查。/fork分支历史断代:执行/fork创建新会话分支时,新目录brain/<fork-cid>/.system_generated/logs/transcript_full.jsonl直接从分叉步号step K(K > 0)开始记录,不会复制父会话0 .. K-1步的 JSONL,且conversation_summaries.db中/fork分支的parent_conversation_id为空。
对比 Claude Code 的无损状态恢复思路
参考主流终端 Agent(如 Claude Code v2.1.x)的上下文管理管线,抗遗忘能力并非单纯依赖“把摘要写得更长”,而是由多层机制协同完成:
| 层级 | Claude Code(v2.1.322–v2.1.325)实测机制 | 本方案在 Antigravity 中的落地与增强 |
|---|---|---|
| 1 | 清理陈旧大体积工具输出(旧 tool_result 替换为已清理占位符) | 由增量预算裁剪与单行工具轨迹折叠(summarize_tool_calls())承担 |
| 2 | 9 段结构化摘要(isCompactSummary: true 第 6 节 6. All user messages 由摘要模型列举,末尾附会话 .jsonl 路径供按需读取) | 确定性增强:直接从 transcript_full.jsonl 逐字提取全量 USER_INPUT 时间线(绕开摘要模型概括缩水) |
| 3 | 局部压缩尾部原话保留(仅交互式分段压缩含 summarizeMetadata 或超长梯级回退时保留未压缩轮次;标准全量 /compact 下不保留原始对话轮次) | 全场景统一保尾:压缩前最近对话滑窗(User + Assistant 原文 + 工具轨迹)逐字回填 |
| 4 | Post-Compact State Rehydration(紧随摘要追加 type: "attachment" 记录,重挂 file / compact_file_reference、invoked_skills、plan_file_reference、task_status) | 压缩后首个 PreInvocation 自动从磁盘实时重读活跃 SKILL/SPEC 与最近改/读文件 |
| 5 | 异常熔断保护 | 严格 Fail-Open:任何异常回退输出 {} 并以 exit 0 放行,绝不阻塞 CLI |
附:Claude Code(v2.1.322–v2.1.325)压缩后会话 JSONL 结构实测依据
在 Claude Code v2.1.322–v2.1.325 中执行标准 /compact(或触发自动压缩)后,可直接观察其落盘的会话 .jsonl 记录序列(无需任何特殊调试工具):
- 压缩边界记录:写入一条
{"type": "system", "subtype": "compact_boundary", "content": "Conversation compacted", "compactMetadata": {"trigger": "manual" | "auto", "preTokens": ..., "postTokens": ...}}。 - 合成摘要轮次(无原始
user消息直传):紧接边界之后仅有一条带"type": "user", "isCompactSummary": true标记的合成摘要消息,正文固定为 9 小节Summary:(1. Primary Request and Intent…6. All user messages…9. Optional Next Step),并在末尾附带完整.jsonl路径提示供模型按需Read。标准全量压缩不会将边界之前的历史user原始消息对象直接搬运到边界之后(仅在消息选择器局部压缩、记录含summarizeMetadata时保留未选中的原始轮次)。 - 压缩后状态附件(
type: "attachment"):紧随isCompactSummary记录之后,自动追加attachment.type为file/compact_file_reference(重读最近访问源码)、invoked_skills、plan_file_reference、task_status等结构化附件,这正是其压缩后不丢失当前代码上下文的核心原因。
核心设计原则只有一句话:<CONTEXT_SUMMARY> 是有损的,但本地磁盘上的 transcript_full.jsonl 和工作区源码是 100% 无损的 Ground Truth;只要在压缩后的第一轮调用前把关键状态自动“回水(Rehydrate)”进 <SYSTEM_MESSAGE>,即可消除压缩断忆。
2. 全局部署与执行时序
2.1 部署位置
配置文件与脚本放置在用户级全局目录(对本机所有工作区、所有新老窗口实时生效,无需重启 agy):
- Hook 注册配置:
~/.gemini/config/hooks.json - 回水执行脚本:
~/.gemini/config/hooks/rehydrate_after_compact.py - 单会话幂等状态缓存:
~/.gemini/antigravity-cli/brain/<conversation-id>/.system_generated/logs/rehydrate_state.json
~/.gemini/config/hooks.json 配置示例(请将 /path/to/home 替换为实际用户主目录绝对路径):
json
{
  "post-compact-rehydrate": {
    "enabled": true,
    "PreInvocation": [
      {
        "type": "command",
        "command": "/usr/bin/python3 /path/to/home/.gemini/config/hooks/rehydrate_after_compact.py",
        "timeout": 10
      }
    ]
  }
}
2.2 生命周期与快速短路时序
PreInvocation 在每次模型推理前都会触发。为了保证平时普通对话零延迟、零额外 Token 开销,脚本仅在刚刚产生新 CHECKPOINT 后的第一轮才执行完整回水:
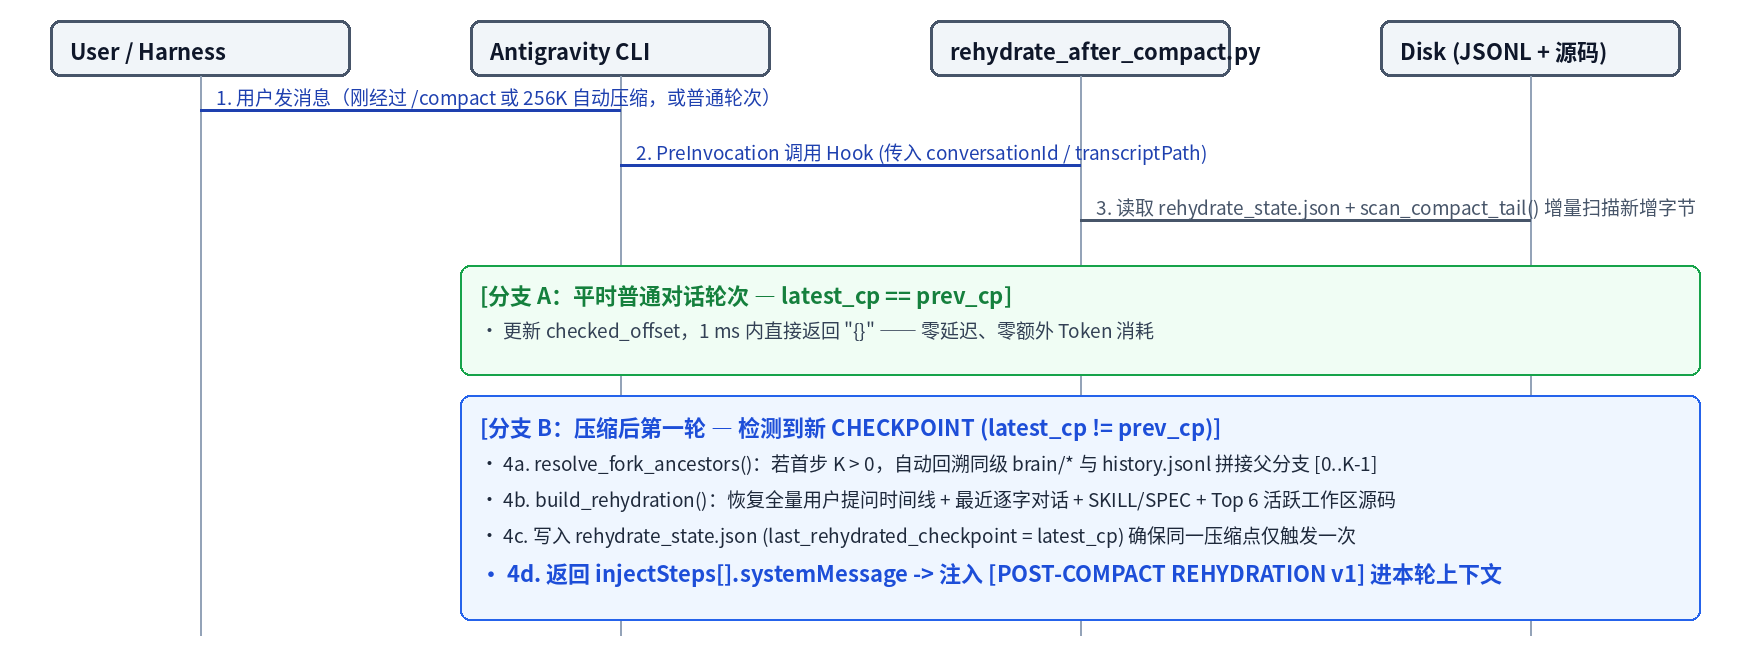
3. 核心机制详解
3.1 毫秒级增量尾扫与存量会话守卫(scan_compact_tail)
字节偏移增量扫描:
rehydrate_state.json记录上次扫描到的文件字节偏移checked_offset与上次已回水的压缩步号last_rehydrated_checkpoint。新轮次到来时,先校验checked_offset - 1处是否为换行符\n(确认日志未被截断重写),随后直接seek(prev_offset)只读本轮新增的几 KB 数据。平时无压缩轮次整次调用耗时约1 ms。存量老会话防误触(
FRESH_CHECKPOINT_MAX_GAP = 8):若一个早已进行到几百步之后的老会话首次挂载本 Hook(尚无rehydrate_state.json),且其最后一次CHECKPOINT距当前最新步号已超过8步,脚本会将其判定为“早已翻篇的历史压缩点”,仅记录状态并返回{},避免在半途突然重放陈旧记录。双重幂等保护:除
rehydrate_state.json外,build_rehydration()还会检查目标CHECKPOINT之后是否已落盘过含[POST-COMPACT REHYDRATION v1标记的SYSTEM_MESSAGE;即使手动删除状态文件,也不会对同一压缩点重复注入。
3.2 跨 /fork 祖先会话链自动溯源与分叉隔离(resolve_fork_ancestors)
当会话由 /fork 创建时,其首条记录满足 cur_first_step > 0(例如从 step 1657 起步),而普通根会话恒从 step 0 开始。脚本通过以下步骤向上递归最多 MAX_FORK_DEPTH = 8 层,自动还原完整线性祖先链:
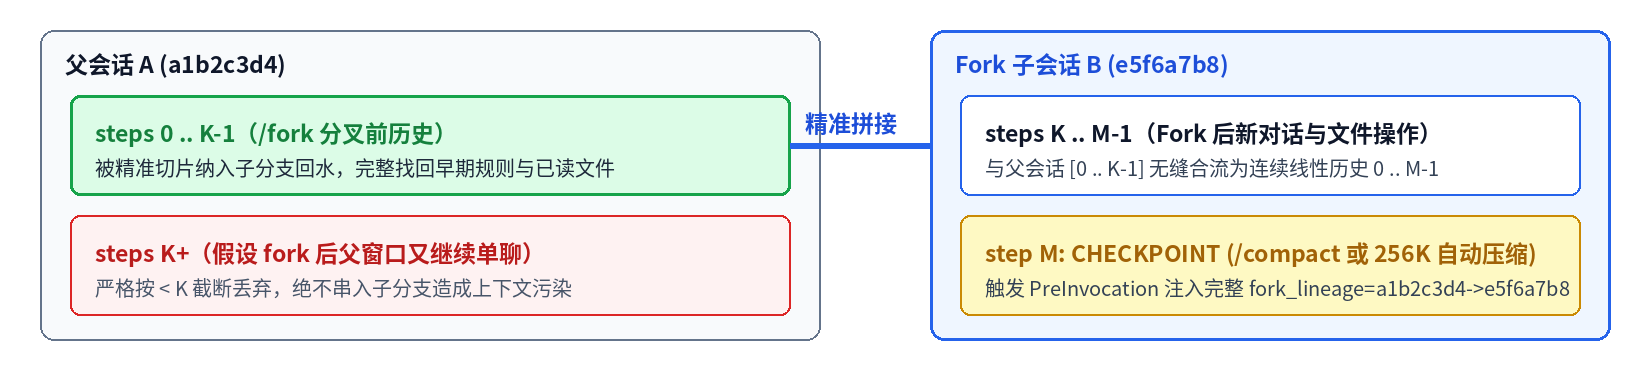
具体寻亲打分策略(无需修改 CLI 二进制):
快路判断与缓存复用:若首行
step_index == 0,直接判定为根会话,返回空祖先列表[](0 额外 I/O)。若rehydrate_state.json中已缓存合法且步号连续的fork_ancestors,直接复用缓存(< 0.5 ms)。候选父分支结构筛选(
find_step_epoch_in_transcript):若当前子分支首步为K(时间T_child),则在同级brain/*目录中检索满足以下结构不变量的候选会话P:
P的起始步号满足0 <= P.first_step <= K - 1;- 先读取
P尾部 64 KB 快速检查末步P.last_step >= K - 1(不满足直接跳过);若P在 fork 后又继续聊了很长导致尾部越过了K - 1,再按字节正则精准检索"step_index": K-1; - 时间因果律校验:
P在step K - 1的时间戳T_prev <= T_child + 5s。
- 多维消歧打分
(fork_cmd_match, same_ws, exact_tip, -time_delta):
fork_cmd_match:读取~/.gemini/antigravity-cli/history.jsonl尾部,若在[T_prev, T_child]窗口内存在针对候选P的{"display": "/fork", "conversationId": P}命令记录,最高优命中;same_ws:子分支与候选父分支处于同一工作区路径;exact_tip:候选父分支恰好停在K - 1步;-time_delta:T_child - T_prev时间差最小者优先。
- 严格分叉隔离与多跳拼接:每段祖先严格按
[min_step, K - 1]切片。即使在/fork之后又回到旧窗口继续发消息,旧窗口>= K的分叉内容也绝不会泄漏进新分支;同时在时间线与逐字对话中自动插入路标--- [/fork branch a1b2c3d4 -> e5f6a7b8 @ step K] ---。
3.3 四层无损回水内容与 Token 预算控制
压缩刚完成时,256K 上下文窗口几乎为空。脚本将回水总字符数控制在约 85K–130K chars(折合约 28K–38K tokens,仅占窗口约 12%–15%),兼顾信息无损度与后续多轮推理空间:
| 注入分节 | 常量配置 | 恢复逻辑与淘汰策略 |
|---|---|---|
| Header 溯源头 | MARKER_PREFIX | 标注 checkpoint=N 与 fork_lineage=a1b2c3d4(0..K-1)->e5f6a7b8(K..M-1) |
| 1. Complete User Request Timeline | BUDGET_ALL_USER_CHARS = 24,000RECENT_USER_VERBATIM_COUNT = 75SHORT_USER_MAX_CHARS = 4 | 最近 75 条 USER_INPUT 100% 逐字保留;75 条之前的早期历史自动滤除 <= 4 字纯中文反馈/省略短句(保留含字母/数字// 的命令与参数),并对 > 800 字长粘贴抽芯留头尾与 JSONL 行号指针;超预算时保留最早 5 条立项原话 + 最近全部提问 |
| 2. Recent Pre-Compaction Verbatim Dialogue | BUDGET_RECENT_TURNS_CHARS = 42,000 | 从 target_cp - 1 向前倒推保留完整的 User / Assistant 逐字对话,并将中间连续工具调用折叠成单行 (Tools run: read_file(...) -> edit_file(...)) |
| 3. Restored Active Skills & Spec Docs | BUDGET_SKILLS_SPECS_CHARS = 20,000 | 会话中触碰过的自定义 SKILL.md 及文件名含 SPEC/PLAN/TEMPLATE/HANDOFF 的 Markdown 文档,从磁盘实时重读(排除内置通用长文档) |
| 4. Restored Active Workspace Files | BUDGET_FILES_TOTAL_CHARS = 48,000BUDGET_SINGLE_FILE_CHARS = 12,000 | 按最后触碰步号倒序选取 Top 3 最近修改文件(edit_file/write_file)+ Top 3 最近读取文件(read_file),从磁盘读取最新内容;超 12,000 字符的文件保留前 68% 头部 + 尾部代码并在中间标注省略字数 |
附:早期极短话轮(<= 4 纯汉字)按长度去噪的语用学、信息论与真实日志消融依据
第 1 节 Complete User Request Timeline 仅抽取出用户侧输入,不包含紧邻的 Assistant 提问。对于滑出最近 75 条配对窗口的早期记录,去除标点符号后 <= 4 个纯汉字(不含字母、数字或 /)的短句几乎不存在可独立复用的自足命题信息,其理论依据与实测数据如下:
- 反馈通道词(Backchannel)无独立命题内容:
- Yngve, V. H. (1970), "On getting a word in edgewise", Papers from the Sixth Regional Meeting of the Chicago Linguistic Society (CLS 6), pp. 567–578:定义对话中的 Backchannel(如简短确认与情绪反馈),指出此类
1~2词极短话轮仅维持话轮交互状态,不承载独立命题语义(Propositional Content)。 - Stolcke, A., Ries, K., Coccaro, N., Shriberg, E., Bates, R., Jurafsky, D., et al. (2000), "Dialogue Act Modeling for Automatic Tagging and Recognition of Conversational Speech", Computational Linguistics, Vol. 26, No. 3, pp. 339–373(ACL Anthology
J00-3003):基于 Switchboard 对话行为语料库实证统计,纯反馈确认类短句(Acknowledge / Backchannel)占自然多轮话轮总数的19%。
- Yngve, V. H. (1970), "On getting a word in edgewise", Papers from the Sixth Regional Meeting of the Chicago Linguistic Society (CLS 6), pp. 567–578:定义对话中的 Backchannel(如简短确认与情绪反馈),指出此类
- 中文多轮对话的指代与省略依赖(Ellipsis & Coreference):
- Su, H., Shen, X., Zhang, R., Sun, F., Hu, P., Niu, C., & Zhou, J. (2019), "Improving Multi-turn Dialogue Modelling with Utterance ReWriter", Proceedings of the 57th Annual Meeting of the Association for Computational Linguistics (ACL 2019), pp. 22–31(ACL Anthology
P19-1003):对中文多轮对话的实证研究指出,超过70%的多轮对话话轮存在指代与信息省略(Ellipsis);诸如“加吧 / 试试 / 如何 / 统一吧”等极短省略句在脱离紧邻上一轮助手话语后,其独立指称对象已不可恢复。
- Su, H., Shen, X., Zhang, R., Sun, F., Hu, P., Niu, C., & Zhou, J. (2019), "Improving Multi-turn Dialogue Modelling with Utterance ReWriter", Proceedings of the 57th Annual Meeting of the Association for Computational Linguistics (ACL 2019), pp. 22–31(ACL Anthology
- 信道容量背景与均匀信息密度假说(UID):
- 冯志伟(1984),《汉字的熵》,《文字改革》1984 年第 4 期,第 12–17 页;冯志伟(1995 / 1996),《汉字的极限熵》,《语文建设通讯》第 50 期第 55–64 页 / 《中文信息》1996 年第 2 期第 53–56 页(另参 孙帆、孙茂松, 2006 大规模语料修正估计约
5.31 bits/字):不计上下文时现代汉字统计熵约为9.65 bits/字,计入上下文约束后的渐近平均极限熵约为4.05–5.31 bits/字。 - Levy, R., & Jaeger, T. F. (2007), "Speakers optimize information density through syntactic reduction", Advances in Neural Information Processing Systems (NIPS 19), pp. 849–856:提出 均匀信息密度(Uniform Information Density, UID) 原则——说话人在传达高惊奇度(High-Surprisal,如推翻默认假设的新增全局约束)信息时会自发增加词长与显式句法标记以防误解,而仅在对上文做高可预测度(Low-Surprisal)顺承确认时才会高度省略至
1~4字。
- 冯志伟(1984),《汉字的熵》,《文字改革》1984 年第 4 期,第 12–17 页;冯志伟(1995 / 1996),《汉字的极限熵》,《语文建设通讯》第 50 期第 55–64 页 / 《中文信息》1996 年第 2 期第 53–56 页(另参 孙帆、孙茂松, 2006 大规模语料修正估计约
- 真实
agy工程会话语料实证统计(N = 850):- 对跨两台开发机的 12 个真实多轮
agy工程会话、共850条去重USER_INPUT进行全量扫描,命中“去标点后<= 4纯汉字且无字母/数字//”的话轮共30条(占比3.53%);逐条人工核验结果中,独立全局约束或自足数据值占0/30(0.0%),100%(30/30) 均为纯反馈确认(如嗯 / 行 / 确认 / 在么)或强依赖紧邻上一轮助手发言的单步动作省略句(如改 / 跑 / 写 / 试试 / 加吧 / 统一吧 / 改一下吧)。
- 对跨两台开发机的 12 个真实多轮
4. 关键工程踩坑与安全边界
- 规避
hookcaller.go的protojson类型反序列化崩溃:
- Antigravity 内部使用
protojson解析 Hook 标准输出,其中StepMetadata.user_markdown并非普通string而是嵌套 Protobuf Message;若传入"metadata": {"user_markdown": "..."}会触发type mismatch: cannot convert string to message导致注入失败。 - 正确的最小返回结构应严格保持为
"injectSteps": [{"systemMessage": {"systemMessage": "..."}}]。
- 规避单条
SystemMessageStep的48 KiB(49,152UTF-8 字节)截断上限:
- 在
agy底层(hooks.InjectSteps$ ightarrow$SystemMessageStringConverter.ToOutputString),单条SYSTEM_MESSAGE步骤超过49,152UTF-8 字节(48 KiB) 时会被硬截断为<truncated N bytes>,在超长中文会话中可能切掉排在末尾的第 4 节源码快照。 - 脚本通过
split_into_inject_chunks()(MAX_INJECT_STEP_BYTES = 44_000)按对话轮次与文件块边界自动拆分为多个独立的injectSteps数组元素,使每条SystemMessageStep均安全处于48 KiB阈值之内,实现四层内容 0 字节截断。
- 跨代际工具名双端兼容(
agyCLI 2.0 + 旧版桌面端 IDE):
- Antigravity CLI(
agy) 实际下发并记录在transcript.jsonl中的原生文件工具为read_file、write_file、edit_file(参数键统一为Path);而早期 Antigravity Desktop IDE(1.x 桌面端) 网页文档使用的是view_file(AbsolutePath)与write_to_file/replace_file_content/multi_replace_file_content(TargetFile)。脚本同时识别两套工具名与路径参数键,双端均可开箱工作。
- 文件过滤黑名单与标准库零依赖:
- 自动跳过图片、PDF、Office 文档、压缩包、模型权重(
.pt/.safetensors/.ply)、数据库文件、大于2 MB的大文件,以及/.system_generated/、/dev/shm/、/tmp/、/antigravity-cli/log/等临时或内部日志路径,确保 6 个源码恢复槽位全部留给真实工程文件。 - 仅依赖 Python 3.9+ 标准库(
json,os,pathlib,re,sys,datetime,unicodedata),无需任何第三方依赖或虚拟环境。
5. 验收与离线调试方法
5.1 交互界面两步验收法
在任意会话(含
/fork分支)中先让模型用read_file读取任意源码文件,随后执行/compact并发送一句简短回复(如继续)。在界面按
Ctrl+O展开System Message,即可看到注入的[POST-COMPACT REHYDRATION v1 | checkpoint=...];若要求模型不调用任何工具直接默写刚才所读文件中的常量或函数定义,模型可直接从第 4 节实时挂载块中一字不差给出。
5.2 命令行离线只读检查
如需在不触发真实对话的前提下检查任意 <conversation-id> 的 /fork 溯源链与回水统计,可运行以下只读脚本:
bash
/usr/bin/python3 -c '
import importlib.util
from pathlib import Path

hook_py = Path.home() / ".gemini/config/hooks/rehydrate_after_compact.py"
spec = importlib.util.spec_from_file_location("rh", str(hook_py))
rh = importlib.util.module_from_spec(spec)
spec.loader.exec_module(rh)

cid = "<your-conversation-id>"
p = Path.home() / f".gemini/antigravity-cli/brain/{cid}/.system_generated/logs/transcript_full.jsonl"
anc = rh.resolve_fork_ancestors(p)
res = rh.build_rehydration(p, up_to_checkpoint_step=999999, ancestors=anc)
print("Ancestors:", anc)
if res:
    msg, stats = res
    print("Stats:", stats)
    print("Header:", msg.splitlines()[0])
'附录:完整可部署源码(rehydrate_after_compact.py)
将以下脚本保存至 ~/.gemini/config/hooks/rehydrate_after_compact.py(赋予可执行权限 chmod +x),并在 ~/.gemini/config/hooks.json 中注册即可开箱即用:
python
#!/usr/bin/env python3
"""Antigravity PreInvocation hook: Post-Compaction State Rehydration (+ /fork lineage stitching)."""
from __future__ import annotations
from datetime import datetime
import json
import os
from pathlib import Path
import re
import sys
from typing import Any
import unicodedata
MARKER_PREFIX = "[POST-COMPACT REHYDRATION v1"
BUDGET_ALL_USER_CHARS = 24_000
BUDGET_RECENT_TURNS_CHARS = 42_000
BUDGET_SKILLS_SPECS_CHARS = 20_000
BUDGET_FILES_TOTAL_CHARS = 48_000
BUDGET_SINGLE_FILE_CHARS = 12_000
RECENT_USER_VERBATIM_COUNT = 75
SHORT_USER_MAX_CHARS = 4
FOLD_PASTE_THRESHOLD_CHARS = 800
FOLD_PASTE_HEAD_CHARS = 300
FOLD_PASTE_TAIL_CHARS = 200
MAX_MODIFIED_FILES = 3
MAX_REFERENCED_FILES = 3
MAX_FORK_DEPTH = 8
FRESH_CHECKPOINT_MAX_GAP = 8
MAX_INJECT_STEP_BYTES = 44_000 # Stay safely under AGY's 49,152-byte (48 KiB) per-SystemMessageStep cap
# agy CLI (2.0) uses read_file/write_file/edit_file + Path;
# legacy Antigravity 1.x Desktop IDE uses view_file + AbsolutePath and write_to_file/replace_file_content + TargetFile.
READ_TOOL_NAMES = {"read_file", "view_file", "view_file_outline", "view_code_item"}
WRITE_TOOL_NAMES = {
"edit_file",
"write_file",
"write_to_file",
"replace_file_content",
"multi_replace_file_content",
}
SKIP_EXTS = {
".png", ".jpg", ".jpeg", ".gif", ".webp", ".bmp", ".svg", ".ico",
".pdf", ".pptx", ".docx", ".xlsx", ".zip", ".tar", ".gz", ".tgz", ".7z",
".mp4", ".mov", ".avi", ".mp3", ".wav", ".ogg",
".so", ".dylib", ".dll", ".exe", ".bin", ".o", ".a",
".pt", ".pth", ".ckpt", ".safetensors", ".onnx", ".npy", ".npz", ".ply",
".db", ".sqlite", ".sqlite3", ".wal", ".shm", ".pb", ".pyc",
}
SKIP_PATH_SUBSTRINGS = (
"/.system_generated/",
"/node_modules/",
"/.git/",
"/__pycache__/",
"/dev/shm/",
"/tmp/",
"/antigravity-cli/log/",
"/antigravity-cli/history.jsonl",
"/antigravity-cli/builtin/skills/antigravity_guide/",
"/antigravity-cli/builtin/skills/agy-customizations/",
)
USER_REQ_RE = re.compile(r"<USER_REQUEST>\s*(.*?)\s*</USER_REQUEST>", re.S)
ASCII_ALNUM_OR_SLASH_RE = re.compile(r"[A-Za-z0-9/]")
def extract_user_text(raw: str) -> str:
if not raw:
return ""
matches = USER_REQ_RE.findall(raw)
if matches:
return "\n".join(m.strip() for m in matches if m.strip())
cleaned = re.sub(r"<ADDITIONAL_METADATA>.*?</ADDITIONAL_METADATA>", "", raw, flags=re.S)
return cleaned.strip()
def is_low_info_short_turn(txt: str) -> bool:
"""Filter ultra-short backchannels/elliptical turns (<=4 non-punct chars, no ASCII/digits/slash)."""
if ASCII_ALNUM_OR_SLASH_RE.search(txt) or any(ch.isdigit() for ch in txt):
return False
core = "".join(
ch for ch in txt
if not ch.isspace() and unicodedata.category(ch)[0] not in ("P", "S", "Z", "C")
)
return len(core) <= SHORT_USER_MAX_CHARS
def fold_user_paste(txt: str, seg_path: Path | None, line_no: int, step_idx: int) -> tuple[str, bool]:
if len(txt) <= FOLD_PASTE_THRESHOLD_CHARS:
return txt, False
omitted = len(txt) - FOLD_PASTE_HEAD_CHARS - FOLD_PASTE_TAIL_CHARS
if omitted <= 120:
return txt, False
loc = f"{seg_path} line {line_no} (step {step_idx})" if seg_path else f"step {step_idx}"
folded = (
f"{txt[:FOLD_PASTE_HEAD_CHARS]}\n"
f" ...[folded {omitted} chars of pasted content; read_file {loc} if exact text needed]...\n"
f"{txt[-FOLD_PASTE_TAIL_CHARS:]}"
)
return folded, True
def extract_tool_file_path(args: dict[str, Any]) -> str:
for key in ("Path", "TargetFile", "AbsolutePath", "File"):
val = args.get(key)
if isinstance(val, str) and val.startswith("/"):
return val
return ""
def summarize_tool_calls(tool_calls: list[dict[str, Any]]) -> str:
parts: list[str] = []
for tc in tool_calls[:8]:
name = tc.get("name", "?")
args = tc.get("args") or {}
if name in READ_TOOL_NAMES or name in WRITE_TOOL_NAMES:
p = extract_tool_file_path(args)
parts.append(f"{name}({os.path.basename(p) or p})")
elif name in ("run_command", "run_in_terminal"):
cmd = (args.get("CommandLine") or args.get("Command") or "").strip().replace("\n", " ")
if len(cmd) > 60:
cmd = cmd[:57] + "..."
parts.append(f"{name}(`{cmd}`)")
else:
parts.append(name)
if len(tool_calls) > 8:
parts.append(f"+{len(tool_calls) - 8} more")
return ", ".join(parts)
def is_eligible_text_file(path_str: str) -> bool:
if not path_str or not path_str.startswith("/"):
return False
for sub in SKIP_PATH_SUBSTRINGS:
if sub in path_str:
return False
if Path(path_str).suffix.lower() in SKIP_EXTS:
return False
p = Path(path_str)
try:
if not p.is_file():
return False
st = p.stat()
return 0 < st.st_size <= 2 * 1024 * 1024
except OSError:
return False
def is_skill_or_spec(path_str: str) -> bool:
name = os.path.basename(path_str)
upper = name.upper()
return name == "SKILL.md" or (
upper.endswith(".MD") and any(k in upper for k in ("SPEC", "PLAN", "TEMPLATE", "HANDOFF"))
)
def read_text_clipped(path_str: str, max_chars: int) -> str | None:
try:
with open(path_str, "r", encoding="utf-8") as f:
text = f.read(max_chars * 3)
except (OSError, UnicodeDecodeError):
return None
if len(text) <= max_chars:
return text
head_len = int(max_chars * 0.68)
tail_len = max_chars - head_len - 80
omitted = len(text) - head_len - max(0, tail_len)
return (
f"{text[:head_len]}\n"
f"... [truncated ~{omitted} chars in middle; read_file for full content] ...\n"
f"{text[-tail_len:] if tail_len > 0 else ''}"
)
def parse_iso_epoch(ts_str: Any) -> float | None:
if not isinstance(ts_str, str) or not ts_str:
return None
try:
norm = ts_str[:-1] + "+00:00" if ts_str.endswith("Z") else ts_str
return datetime.fromisoformat(norm).timestamp()
except ValueError:
return None
def infer_cid_from_transcript_path(tpath: Path) -> str:
parts = tpath.parts
if len(parts) >= 4 and parts[-2] == "logs" and parts[-3] == ".system_generated":
return parts[-4]
return tpath.parent.name
def read_first_step_info(jsonl_path: Path) -> tuple[int, float | None] | None:
try:
with open(jsonl_path, "rb") as f:
for _ in range(16):
raw = f.readline()
if not raw:
return None
if not raw.strip():
continue
obj = json.loads(raw.decode("utf-8", "replace"))
sidx = obj.get("step_index")
if isinstance(sidx, int):
return sidx, parse_iso_epoch(obj.get("created_at"))
except (OSError, json.JSONDecodeError):
return None
return None
def find_step_epoch_in_transcript(jsonl_path: Path, target_step: int) -> tuple[int, float | None] | None:
try:
st_size = jsonl_path.stat().st_size
if st_size <= 0:
return None
tail_window = 65536
with open(jsonl_path, "rb") as fb:
seek_pos = max(0, st_size - tail_window)
fb.seek(seek_pos)
chunk = fb.read()
raw_lines = chunk.splitlines()
if seek_pos > 0 and raw_lines:
raw_lines = raw_lines[1:]
last_step: int | None = None
for raw in reversed(raw_lines):
if not raw.strip():
continue
try:
obj = json.loads(raw.decode("utf-8", "replace"))
except json.JSONDecodeError:
continue
sidx = obj.get("step_index")
if not isinstance(sidx, int):
continue
if last_step is None:
last_step = sidx
if last_step < target_step:
return None
if sidx == target_step:
return last_step, parse_iso_epoch(obj.get("created_at"))
if sidx < target_step:
return None
step_pat = re.compile(rb'"step_index"\s*:\s*' + str(target_step).encode("ascii") + rb"\b")
with open(jsonl_path, "rb") as fb:
for raw in fb:
if step_pat.search(raw[:160]):
try:
obj = json.loads(raw.decode("utf-8", "replace"))
except json.JSONDecodeError:
continue
if obj.get("step_index") == target_step:
return (last_step or target_step), parse_iso_epoch(obj.get("created_at"))
return None
except OSError:
return None
def load_history_fork_hints(brain_dir: Path) -> tuple[dict[str, set[str]], list[tuple[str, float]]]:
cid_workspaces: dict[str, set[str]] = {}
fork_events: list[tuple[str, float]] = []
hist_path = brain_dir.parent / "history.jsonl"
if not hist_path.is_file():
return cid_workspaces, fork_events
try:
st_size = hist_path.stat().st_size
with open(hist_path, "rb") as fb:
seek_pos = max(0, st_size - 524288)
fb.seek(seek_pos)
lines = fb.read().splitlines()
if seek_pos > 0 and lines:
lines = lines[1:]
for raw in lines:
if not raw.strip():
continue
try:
obj = json.loads(raw.decode("utf-8", "replace"))
except json.JSONDecodeError:
continue
cid = obj.get("conversationId")
ws = obj.get("workspace")
if isinstance(cid, str) and cid:
if isinstance(ws, str) and ws:
cid_workspaces.setdefault(cid, set()).add(ws)
if obj.get("display") == "/fork" and isinstance(obj.get("timestamp"), (int, float)):
fork_events.append((cid, float(obj["timestamp"]) / 1000.0))
except OSError:
pass
return cid_workspaces, fork_events
def validate_cached_ancestors(cached: Any, cur_first_step: int) -> list[dict[str, Any]] | None:
if not isinstance(cached, list) or not cached:
return None
cleaned: list[dict[str, Any]] = []
for item in cached:
if not isinstance(item, dict):
return None
p_str, cid, s_min, s_max = item.get("path"), item.get("cid"), item.get("min_step"), item.get("max_step")
if (
not isinstance(p_str, str) or not isinstance(cid, str)
or not isinstance(s_min, int) or not isinstance(s_max, int)
or s_min > s_max or not Path(p_str).is_file()
):
return None
cleaned.append({"cid": cid, "path": p_str, "min_step": s_min, "max_step": s_max})
for idx in range(len(cleaned) - 1):
if cleaned[idx]["max_step"] + 1 != cleaned[idx + 1]["min_step"]:
return None
return cleaned if cleaned[-1]["max_step"] + 1 == cur_first_step else None
def resolve_fork_ancestors(full_path: Path, cached_ancestors: Any = None) -> list[dict[str, Any]]:
first_info = read_first_step_info(full_path)
if first_info is None or first_info[0] <= 0:
return []
cur_first_step, cur_first_epoch = first_info
valid_cache = validate_cached_ancestors(cached_ancestors, cur_first_step)
if valid_cache is not None:
return valid_cache
parts = full_path.parts
if len(parts) < 5 or parts[-2] != "logs" or parts[-3] != ".system_generated":
return []
brain_dir = full_path.parents[3]
if not brain_dir.is_dir():
return []
cid_workspaces, fork_events = load_history_fork_hints(brain_dir)
cur_cid = infer_cid_from_transcript_path(full_path)
visited: set[str] = {cur_cid}
ancestors_rev: list[dict[str, Any]] = []
child_cid, child_first_step, child_first_epoch = cur_cid, cur_first_step, cur_first_epoch
for _ in range(MAX_FORK_DEPTH):
if child_first_step <= 0:
break
need_prev = child_first_step - 1
child_ws = cid_workspaces.get(child_cid, set())
best_score: tuple[int, int, int, float] | None = None
best_seg: tuple[str, Path, int, float | None] | None = None
try:
cand_dirs = list(brain_dir.iterdir())
except OSError:
break
for cand_dir in cand_dirs:
cand_cid = cand_dir.name
if cand_cid in visited or not cand_dir.is_dir():
continue
cand_logs = cand_dir / ".system_generated" / "logs"
cand_full = cand_logs / "transcript_full.jsonl"
if not cand_full.is_file():
cand_full = cand_logs / "transcript.jsonl"
if not cand_full.is_file():
continue
cand_first = read_first_step_info(cand_full)
if cand_first is None or cand_first[0] < 0 or cand_first[0] > need_prev:
continue
hit = find_step_epoch_in_transcript(cand_full, need_prev)
if hit is None:
continue
cand_last_step, prev_epoch = hit
if child_first_epoch is not None and prev_epoch is not None:
if prev_epoch > child_first_epoch + 5.0:
continue
time_delta = max(0.0, child_first_epoch - prev_epoch)
else:
time_delta = 1e9
fork_cmd_match = int(any(
fcid == cand_cid
and (prev_epoch is None or fts >= prev_epoch - 5.0)
and (child_first_epoch is None or fts <= child_first_epoch + 5.0)
for fcid, fts in fork_events
))
cand_ws = cid_workspaces.get(cand_cid, set())
same_ws = int(bool(child_ws and cand_ws and (child_ws & cand_ws)))
exact_tip = int(cand_last_step == need_prev)
score = (fork_cmd_match, same_ws, exact_tip, -time_delta)
if best_score is None or score > best_score:
best_score = score
best_seg = (cand_cid, cand_full, cand_first[0], cand_first[1])
if best_seg is None:
break
p_cid, p_path, p_first_step, p_first_epoch = best_seg
ancestors_rev.append({"cid": p_cid, "path": str(p_path), "min_step": p_first_step, "max_step": need_prev})
visited.add(p_cid)
child_cid, child_first_step, child_first_epoch = p_cid, p_first_step, p_first_epoch
if p_first_step <= 0:
break
ancestors_rev.reverse()
return ancestors_rev
def find_transcript_files(payload: dict[str, Any]) -> tuple[Path | None, Path | None, Path | None]:
tp = payload.get("transcriptPath") or ""
ad = payload.get("artifactDirectoryPath") or ""
cid = payload.get("conversationId") or ""
candidates: list[Path] = []
if tp:
candidates.append(Path(tp))
if ad:
candidates.append(Path(ad) / ".system_generated" / "logs" / "transcript.jsonl")
if cid:
candidates.append(
Path.home() / ".gemini" / "antigravity-cli" / "brain" / cid / ".system_generated" / "logs" / "transcript.jsonl"
)
compact_path = next((c for c in candidates if c.is_file()), None)
if compact_path is None:
return None, None, None
logs_dir = compact_path.parent
full_path = logs_dir / "transcript_full.jsonl"
return compact_path, (full_path if full_path.is_file() else compact_path), logs_dir / "rehydrate_state.json"
def scan_compact_tail(compact_path: Path, prev_offset: int, prev_cp: int | None) -> tuple[int | None, int, int]:
st_size = compact_path.stat().st_size
if st_size == prev_offset and prev_offset > 0:
return prev_cp, -1, st_size
use_incremental = False
if 0 < prev_offset < st_size:
with open(compact_path, "rb") as fb_chk:
fb_chk.seek(prev_offset - 1)
use_incremental = fb_chk.read(1) == b"\n"
latest_cp = prev_cp if use_incremental else None
max_step = -1
with open(compact_path, "rb") as fb:
if use_incremental:
fb.seek(prev_offset)
for raw_line in fb:
if not raw_line.strip():
continue
if b'"CHECKPOINT"' in raw_line:
try:
obj = json.loads(raw_line.decode("utf-8", "replace"))
sidx = obj.get("step_index", -1)
max_step = max(max_step, sidx)
if obj.get("type") == "CHECKPOINT":
latest_cp = sidx
except json.JSONDecodeError:
pass
else:
m = re.search(rb'"step_index"\s*:\s*(\d+)', raw_line[:128])
if m:
max_step = max(max_step, int(m.group(1)))
return latest_cp, max_step, st_size
def format_user_timeline(
user_messages: list[tuple[int, str, Path | None, int]],
) -> tuple[str, int, int, int, int]:
total_real = sum(1 for _, txt, _, _ in user_messages if not txt.startswith("--- [/fork branch "))
def render_pass(fold_before_recent: int) -> tuple[list[str], int, int, int]:
lines: list[str] = []
idx = 0
kept_real = 0
filtered_short = 0
folded_pastes = 0
verbatim_cutoff = total_real - RECENT_USER_VERBATIM_COUNT
fold_cutoff = total_real - fold_before_recent
for step_s, txt, spath, lno in user_messages:
if txt.startswith("--- [/fork branch "):
lines.append(f"- {txt}")
continue
idx += 1
if idx > 1 and idx <= verbatim_cutoff and is_low_info_short_turn(txt):
filtered_short += 1
continue
out_txt = txt
if idx <= fold_cutoff:
out_txt, did_fold = fold_user_paste(txt, spath, lno, step_s)
if did_fold:
folded_pastes += 1
kept_real += 1
lines.append(f"- [#{idx} @ step {step_s}]: {out_txt}")
return lines, kept_real, filtered_short, folded_pastes
user_lines, kept_count, filtered_short_count, folded_paste_count = render_pass(RECENT_USER_VERBATIM_COUNT)
all_user_block = "\n".join(user_lines)
if len(all_user_block) > BUDGET_ALL_USER_CHARS and total_real > 10:
user_lines, kept_count, filtered_short_count, folded_paste_count = render_pass(10)
all_user_block = "\n".join(user_lines)
if len(all_user_block) > BUDGET_ALL_USER_CHARS and len(user_lines) > 8:
head_part = "\n".join(user_lines[:5])
tail_lines: list[str] = []
used = len(head_part) + 100
for ul in reversed(user_lines[5:]):
if used + len(ul) + 1 > BUDGET_ALL_USER_CHARS:
break
tail_lines.append(ul)
used += len(ul) + 1
tail_lines.reverse()
all_user_block = f"{head_part}\n- [... earlier middle prompts omitted for budget ...]\n" + "\n".join(tail_lines)
return all_user_block, total_real, kept_count, filtered_short_count, folded_paste_count
def build_rehydration(
full_path: Path,
up_to_checkpoint_step: int | None = None,
ancestors: list[dict[str, Any]] | None = None,
) -> tuple[str, dict[str, Any]] | None:
checkpoints: list[int] = []
already_rehydrated_after: set[int] = set()
with open(full_path, "r", encoding="utf-8", errors="replace") as f:
last_cp: int | None = None
for line in f:
if not line.strip():
continue
try:
obj = json.loads(line)
except json.JSONDecodeError:
continue
step_idx = obj.get("step_index", -1)
if up_to_checkpoint_step is not None and step_idx > up_to_checkpoint_step:
break
stype = obj.get("type")
if stype == "CHECKPOINT":
checkpoints.append(step_idx)
last_cp = step_idx
elif stype == "SYSTEM_MESSAGE" and last_cp is not None:
if MARKER_PREFIX in str(obj.get("content") or ""):
already_rehydrated_after.add(last_cp)
if not checkpoints:
return None
target_cp = checkpoints[-1]
if up_to_checkpoint_step is None and target_cp in already_rehydrated_after:
return None
cur_cid = infer_cid_from_transcript_path(full_path)
cur_first_info = read_first_step_info(full_path)
cur_first_step = cur_first_info[0] if cur_first_info is not None else 0
resolved_ancestors = ancestors if ancestors is not None else resolve_fork_ancestors(full_path)
segments: list[dict[str, Any]] = [
*resolved_ancestors,
{"cid": cur_cid, "path": str(full_path), "min_step": cur_first_step, "max_step": target_cp - 1},
]
user_messages: list[tuple[int, str, Path | None, int]] = []
dialogue_entries: list[str] = []
modified_touch: dict[str, int] = {}
read_touch: dict[str, int] = {}
skill_spec_touch: dict[str, int] = {}
pending_tools: list[str] = []
for seg_idx, seg in enumerate(segments):
seg_path = Path(seg["path"])
seg_min = int(seg["min_step"])
seg_max = min(int(seg["max_step"]), target_cp - 1)
if seg_min > seg_max or not seg_path.is_file():
continue
if seg_idx > 0:
fork_banner = f"--- [/fork branch {str(segments[seg_idx - 1]['cid'])[:8]} -> {str(seg['cid'])[:8]} @ step {seg_min}] ---"
user_messages.append((seg_min, fork_banner, None, 0))
dialogue_entries.append(fork_banner)
with open(seg_path, "r", encoding="utf-8", errors="replace") as f:
for line_no, line in enumerate(f, 1):
if not line.strip():
continue
try:
obj = json.loads(line)
except json.JSONDecodeError:
continue
step_idx = obj.get("step_index", -1)
if step_idx < seg_min:
continue
if step_idx > seg_max:
break
stype = obj.get("type")
if stype == "USER_INPUT":
utext = extract_user_text(str(obj.get("content") or ""))
if utext:
user_messages.append((step_idx, utext, seg_path, line_no))
dialogue_entries.append(f"[Step {step_idx} | User]:\n{utext}")
pending_tools.clear()
elif stype == "PLANNER_RESPONSE":
tcs = obj.get("tool_calls") or []
if tcs:
pending_tools.append(summarize_tool_calls(tcs))
for tc in tcs:
tname = tc.get("name")
fpath = extract_tool_file_path(tc.get("args") or {})
if fpath:
if is_skill_or_spec(fpath) and is_eligible_text_file(fpath):
skill_spec_touch[fpath] = step_idx
elif tname in WRITE_TOOL_NAMES:
modified_touch[fpath] = step_idx
elif tname in READ_TOOL_NAMES:
read_touch[fpath] = step_idx
mcontent = str(obj.get("content") or "").strip()
if mcontent:
tool_prefix = ""
if pending_tools:
joined_tools = " -> ".join(pending_tools[:6])
if len(pending_tools) > 6:
joined_tools += f" (+{len(pending_tools) - 6} steps)"
tool_prefix = f" (Tools run: {joined_tools})\n"
pending_tools.clear()
dialogue_entries.append(f"[Step {step_idx} | Assistant]:\n{tool_prefix}{mcontent}")
if pending_tools:
dialogue_entries.append(f"[Pre-Compaction In-Progress Tools]: {' -> '.join(pending_tools[:6])}")
(
all_user_block,
real_user_count,
kept_user_count,
filtered_short_count,
folded_paste_count,
) = format_user_timeline(user_messages)
kept_turns: list[str] = []
used_turns = 0
for entry in reversed(dialogue_entries):
clipped_entry = entry if len(entry) <= 6000 else (entry[:4500] + "\n...[turn clipped]...\n" + entry[-1200:])
if used_turns + len(clipped_entry) > BUDGET_RECENT_TURNS_CHARS and kept_turns:
break
kept_turns.append(clipped_entry)
used_turns += len(clipped_entry) + 2
kept_turns.reverse()
skill_blocks: list[str] = []
used_skills = 0
for spath, sstep in sorted(skill_spec_touch.items(), key=lambda x: x[1], reverse=True):
if not is_eligible_text_file(spath):
continue
rem = BUDGET_SKILLS_SPECS_CHARS - used_skills
if rem < 800:
break
content = read_text_clipped(spath, min(BUDGET_SINGLE_FILE_CHARS, rem))
if content:
block = f"### `{spath}` (touched @ step {sstep})\n```\n{content}\n```"
skill_blocks.append(block)
used_skills += len(block)
mod_candidates = [
(p, st) for p, st in sorted(modified_touch.items(), key=lambda x: x[1], reverse=True)
if p not in skill_spec_touch and is_eligible_text_file(p)
][:MAX_MODIFIED_FILES]
mod_set = {p for p, _ in mod_candidates}
ref_candidates = [
(p, st) for p, st in sorted(read_touch.items(), key=lambda x: x[1], reverse=True)
if p not in skill_spec_touch and p not in mod_set and is_eligible_text_file(p)
][:MAX_REFERENCED_FILES]
file_blocks: list[str] = []
used_files = 0
for role_label, items in (("Modified", mod_candidates), ("Referenced", ref_candidates)):
for fpath, fstep in items:
rem = BUDGET_FILES_TOTAL_CHARS - used_files
if rem < 1000:
break
content = read_text_clipped(fpath, min(BUDGET_SINGLE_FILE_CHARS, rem))
if content:
block = f"### [{role_label} @ step {fstep}] `{fpath}`\n```\n{content}\n```"
file_blocks.append(block)
used_files += len(block)
lineage_tag = ""
if resolved_ancestors:
chain_parts = [
f"{str(seg['cid'])[:8]}({seg['min_step']}..{min(int(seg['max_step']), target_cp - 1)})"
for seg in segments
if int(seg["min_step"]) <= min(int(seg["max_step"]), target_cp - 1)
]
lineage_tag = f" | fork_lineage={'->'.join(chain_parts)}"
if filtered_short_count > 0 or folded_paste_count > 0:
sec1_hdr = (
f"## 1. Complete User Request Timeline "
f"({kept_user_count}/{real_user_count} messages; last {min(real_user_count, RECENT_USER_VERBATIM_COUNT)} verbatim, "
f"{filtered_short_count} older <={SHORT_USER_MAX_CHARS}-char elliptical turns filtered)"
)
else:
sec1_hdr = f"## 1. Complete User Request Timeline ({real_user_count} messages verbatim)"
sections = [
f"{MARKER_PREFIX} | checkpoint={target_cp}{lineage_tag}]",
(
"The harness just compacted earlier history into `<CONTEXT_SUMMARY>`, which is lossy. "
"Below is the lossless state automatically rehydrated from `transcript_full.jsonl` "
"(including any `/fork` ancestor transcripts) and disk. "
"Whenever `<CONTEXT_SUMMARY>` conflicts with or omits details present in these verbatim records "
"or restored files, ALWAYS trust the verbatim text and live file contents below."
),
f"{sec1_hdr}\n{all_user_block}",
(
f"## 2. Recent Pre-Compaction Verbatim Dialogue ({len(kept_turns)} entries kept verbatim)\n"
"*(Note: The messages below are the actual pre-compaction turns kept verbatim.)*\n\n"
+ "\n\n".join(kept_turns)
),
]
if skill_blocks:
sections.append("## 3. Restored Active Skills & Spec Docs\n" + "\n\n".join(skill_blocks))
if file_blocks:
sections.append("## 4. Restored Active Workspace Files (Live Disk Read)\n" + "\n\n".join(file_blocks))
full_msg = "\n\n".join(sections)
chunks = split_into_inject_chunks(sections, max_bytes=MAX_INJECT_STEP_BYTES, checkpoint=target_cp)
return full_msg, {
"checkpoint": target_cp,
"fork_hops": len(resolved_ancestors),
"user_msgs": real_user_count,
"kept_user_msgs": kept_user_count,
"filtered_short_msgs": filtered_short_count,
"folded_paste_msgs": folded_paste_count,
"kept_turns": len(kept_turns),
"skills": len(skill_blocks),
"files": len(file_blocks),
"chars": len(full_msg),
"utf8_bytes": len(full_msg.encode("utf-8")),
"inject_chunks": len(chunks),
"chunks": chunks,
"est_tokens": len(full_msg) // 3,
}
def _split_oversized_block(text: str, max_bytes: int) -> list[str]:
if len(text.encode("utf-8")) <= max_bytes:
return [text]
pieces: list[str] = []
cur_lines: list[str] = []
cur_bytes = 0
for line in text.split("\n"):
lb = len(line.encode("utf-8")) + 1
if lb > max_bytes:
if cur_lines:
pieces.append("\n".join(cur_lines))
cur_lines, cur_bytes = [], 0
# Hard-slice an ultra-long single line safely by characters
buf: list[str] = []
bb = 0
for ch in line:
cb = len(ch.encode("utf-8"))
if bb + cb > max_bytes - 64 and buf:
pieces.append("".join(buf))
buf, bb = [], 0
buf.append(ch)
bb += cb
if buf:
pieces.append("".join(buf))
continue
if cur_lines and cur_bytes + lb > max_bytes:
pieces.append("\n".join(cur_lines))
cur_lines, cur_bytes = [line], lb
else:
cur_lines.append(line)
cur_bytes += lb
if cur_lines:
pieces.append("\n".join(cur_lines))
return pieces
def split_into_inject_chunks(
sections: list[str],
max_bytes: int = MAX_INJECT_STEP_BYTES,
checkpoint: int | None = None,
) -> list[str]:
"""Pack sections into <=max_bytes UTF-8 chunks so no single SystemMessageStep hits AGY's 48 KiB cap."""
header_reserve = 96
limit = max(4096, max_bytes - header_reserve)
atomic_blocks: list[str] = []
for sec in sections:
if len(sec.encode("utf-8")) <= limit:
atomic_blocks.append(sec)
else:
# Prefer splitting on turn/file boundaries so fenced code blocks stay intact
sub_items = re.split(r"\n\n(?=### |\[Step |\[Pre-Compaction |--- \[/fork )", sec)
for item in sub_items:
if len(item.encode("utf-8")) <= limit:
atomic_blocks.append(item)
else:
for para in item.split("\n\n"):
atomic_blocks.extend(_split_oversized_block(para, limit))
raw_chunks: list[str] = []
cur_parts: list[str] = []
cur_bytes = 0
for blk in atomic_blocks:
bb = len(blk.encode("utf-8"))
sep = 2 if cur_parts else 0
if cur_parts and cur_bytes + sep + bb > limit:
raw_chunks.append("\n\n".join(cur_parts))
cur_parts = [blk]
cur_bytes = bb
else:
cur_parts.append(blk)
cur_bytes += sep + bb
if cur_parts:
raw_chunks.append("\n\n".join(cur_parts))
if len(raw_chunks) <= 1:
return raw_chunks
cp_note = f" | checkpoint={checkpoint}" if checkpoint is not None else ""
total = len(raw_chunks)
tagged: list[str] = []
for idx, ch in enumerate(raw_chunks, 1):
if idx == 1:
tagged.append(ch)
else:
tagged.append(f"[POST-COMPACT REHYDRATION cont. part {idx}/{total}{cp_note}]\n\n{ch}")
return tagged
def save_state(state_path: Path, cp: int | None, offset: int, fork_ancestors: list[dict[str, Any]] | None = None) -> None:
try:
data: dict[str, Any] = {"last_rehydrated_checkpoint": cp, "checked_offset": offset}
if fork_ancestors:
data["fork_ancestors"] = fork_ancestors
state_path.write_text(json.dumps(data, indent=2), encoding="utf-8")
except OSError:
pass
def main() -> None:
try:
raw_in = sys.stdin.read()
if not raw_in.strip():
print("{}")
return
payload = json.loads(raw_in)
compact_path, full_path, state_path = find_transcript_files(payload)
if compact_path is None or full_path is None or state_path is None:
print("{}")
return
had_state = state_path.is_file()
state: dict[str, Any] = {}
if had_state:
try:
state = json.loads(state_path.read_text(encoding="utf-8"))
except (OSError, json.JSONDecodeError):
had_state = False
prev_cp = state.get("last_rehydrated_checkpoint")
prev_offset = int(state.get("checked_offset") or 0)
cached_ancestors = state.get("fork_ancestors")
latest_cp, max_step, new_offset = scan_compact_tail(compact_path, prev_offset, prev_cp)
if latest_cp is None or latest_cp == prev_cp:
save_state(state_path, latest_cp, new_offset, cached_ancestors)
print("{}")
return
if not had_state and max_step > latest_cp and (max_step - latest_cp) > FRESH_CHECKPOINT_MAX_GAP:
ancestors = resolve_fork_ancestors(full_path, cached_ancestors)
save_state(state_path, latest_cp, new_offset, ancestors)
print("{}")
return
ancestors = resolve_fork_ancestors(full_path, cached_ancestors)
res = build_rehydration(full_path, ancestors=ancestors)
save_state(state_path, latest_cp, new_offset, ancestors)
if res is None:
print("{}")
return
full_msg, stats = res
chunks = stats.get("chunks") or [full_msg]
print(
json.dumps(
{"injectSteps": [{"systemMessage": {"systemMessage": c}} for c in chunks]},
ensure_ascii=False,
)
)
except Exception:
print("{}")
if __name__ == "__main__":
main()
```\n{content}\n```"
skill_blocks.append(block)
used_skills += len(block)
mod_candidates = [
(p, st) for p, st in sorted(modified_touch.items(), key=lambda x: x[1], reverse=True)
if p not in skill_spec_touch and is_eligible_text_file(p)
][:MAX_MODIFIED_FILES]
mod_set = {p for p, _ in mod_candidates}
ref_candidates = [
(p, st) for p, st in sorted(read_touch.items(), key=lambda x: x[1], reverse=True)
if p not in skill_spec_touch and p not in mod_set and is_eligible_text_file(p)
][:MAX_REFERENCED_FILES]
file_blocks: list[str] = []
used_files = 0
for role_label, items in (("Modified", mod_candidates), ("Referenced", ref_candidates)):
for fpath, fstep in items:
rem = BUDGET_FILES_TOTAL_CHARS - used_files
if rem < 1000:
break
content = read_text_clipped(fpath, min(BUDGET_SINGLE_FILE_CHARS, rem))
if content:
block = f"### [{role_label} @ step {fstep}] `{fpath}`\n```\n{content}\n```"
file_blocks.append(block)
used_files += len(block)
lineage_tag = ""
if resolved_ancestors:
chain_parts = [
f"{str(seg['cid'])[:8]}({seg['min_step']}..{min(int(seg['max_step']), target_cp - 1)})"
for seg in segments
if int(seg["min_step"]) <= min(int(seg["max_step"]), target_cp - 1)
]
lineage_tag = f" | fork_lineage={'->'.join(chain_parts)}"
if filtered_short_count > 0 or folded_paste_count > 0:
sec1_hdr = (
f"## 1. Complete User Request Timeline "
f"({kept_user_count}/{real_user_count} messages; last {min(real_user_count, RECENT_USER_VERBATIM_COUNT)} verbatim, "
f"{filtered_short_count} older <={SHORT_USER_MAX_CHARS}-char elliptical turns filtered)"
)
else:
sec1_hdr = f"## 1. Complete User Request Timeline ({real_user_count} messages verbatim)"
sections = [
f"{MARKER_PREFIX} | checkpoint={target_cp}{lineage_tag}]",
(
"The harness just compacted earlier history into `<CONTEXT_SUMMARY>`, which is lossy. "
"Below is the lossless state automatically rehydrated from `transcript_full.jsonl` "
"(including any `/fork` ancestor transcripts) and disk. "
"Whenever `<CONTEXT_SUMMARY>` conflicts with or omits details present in these verbatim records "
"or restored files, ALWAYS trust the verbatim text and live file contents below."
),
f"{sec1_hdr}\n{all_user_block}",
(
f"## 2. Recent Pre-Compaction Verbatim Dialogue ({len(kept_turns)} entries kept verbatim)\n"
"*(Note: The messages below are the actual pre-compaction turns kept verbatim.)*\n\n"
+ "\n\n".join(kept_turns)
),
]
if skill_blocks:
sections.append("## 3. Restored Active Skills & Spec Docs\n" + "\n\n".join(skill_blocks))
if file_blocks:
sections.append("## 4. Restored Active Workspace Files (Live Disk Read)\n" + "\n\n".join(file_blocks))
full_msg = "\n\n".join(sections)
return full_msg, {
"checkpoint": target_cp,
"fork_hops": len(resolved_ancestors),
"user_msgs": real_user_count,
"kept_user_msgs": kept_user_count,
"filtered_short_msgs": filtered_short_count,
"folded_paste_msgs": folded_paste_count,
"kept_turns": len(kept_turns),
"skills": len(skill_blocks),
"files": len(file_blocks),
"chars": len(full_msg),
"est_tokens": len(full_msg) // 3,
}
def save_state(state_path: Path, cp: int | None, offset: int, fork_ancestors: list[dict[str, Any]] | None = None) -> None:
try:
data: dict[str, Any] = {"last_rehydrated_checkpoint": cp, "checked_offset": offset}
if fork_ancestors:
data["fork_ancestors"] = fork_ancestors
state_path.write_text(json.dumps(data, indent=2), encoding="utf-8")
except OSError:
pass
def main() -> None:
try:
raw_in = sys.stdin.read()
if not raw_in.strip():
print("{}")
return
payload = json.loads(raw_in)
compact_path, full_path, state_path = find_transcript_files(payload)
if compact_path is None or full_path is None or state_path is None:
print("{}")
return
had_state = state_path.is_file()
state: dict[str, Any] = {}
if had_state:
try:
state = json.loads(state_path.read_text(encoding="utf-8"))
except (OSError, json.JSONDecodeError):
had_state = False
prev_cp = state.get("last_rehydrated_checkpoint")
prev_offset = int(state.get("checked_offset") or 0)
cached_ancestors = state.get("fork_ancestors")
latest_cp, max_step, new_offset = scan_compact_tail(compact_path, prev_offset, prev_cp)
if latest_cp is None or latest_cp == prev_cp:
save_state(state_path, latest_cp, new_offset, cached_ancestors)
print("{}")
return
if not had_state and max_step > latest_cp and (max_step - latest_cp) > FRESH_CHECKPOINT_MAX_GAP:
ancestors = resolve_fork_ancestors(full_path, cached_ancestors)
save_state(state_path, latest_cp, new_offset, ancestors)
print("{}")
return
ancestors = resolve_fork_ancestors(full_path, cached_ancestors)
res = build_rehydration(full_path, ancestors=ancestors)
save_state(state_path, latest_cp, new_offset, ancestors)
if res is None:
print("{}")
return
full_msg, _ = res
print(json.dumps({"injectSteps": [{"systemMessage": {"systemMessage": full_msg}}]}, ensure_ascii=False))
except Exception:
print("{}")
if __name__ == "__main__":
main()